

Want an AI agent that can look at an image and read the text around it? This guide shows you how to build multimodal AI agents on AWS using Amazon Rekognition and Amazon Comprehend. It’s written for developers, cloud engineers, and ML folks who know the AWS basics and want a working agent, not a theory lecture.
Here’s what we’ll cover:
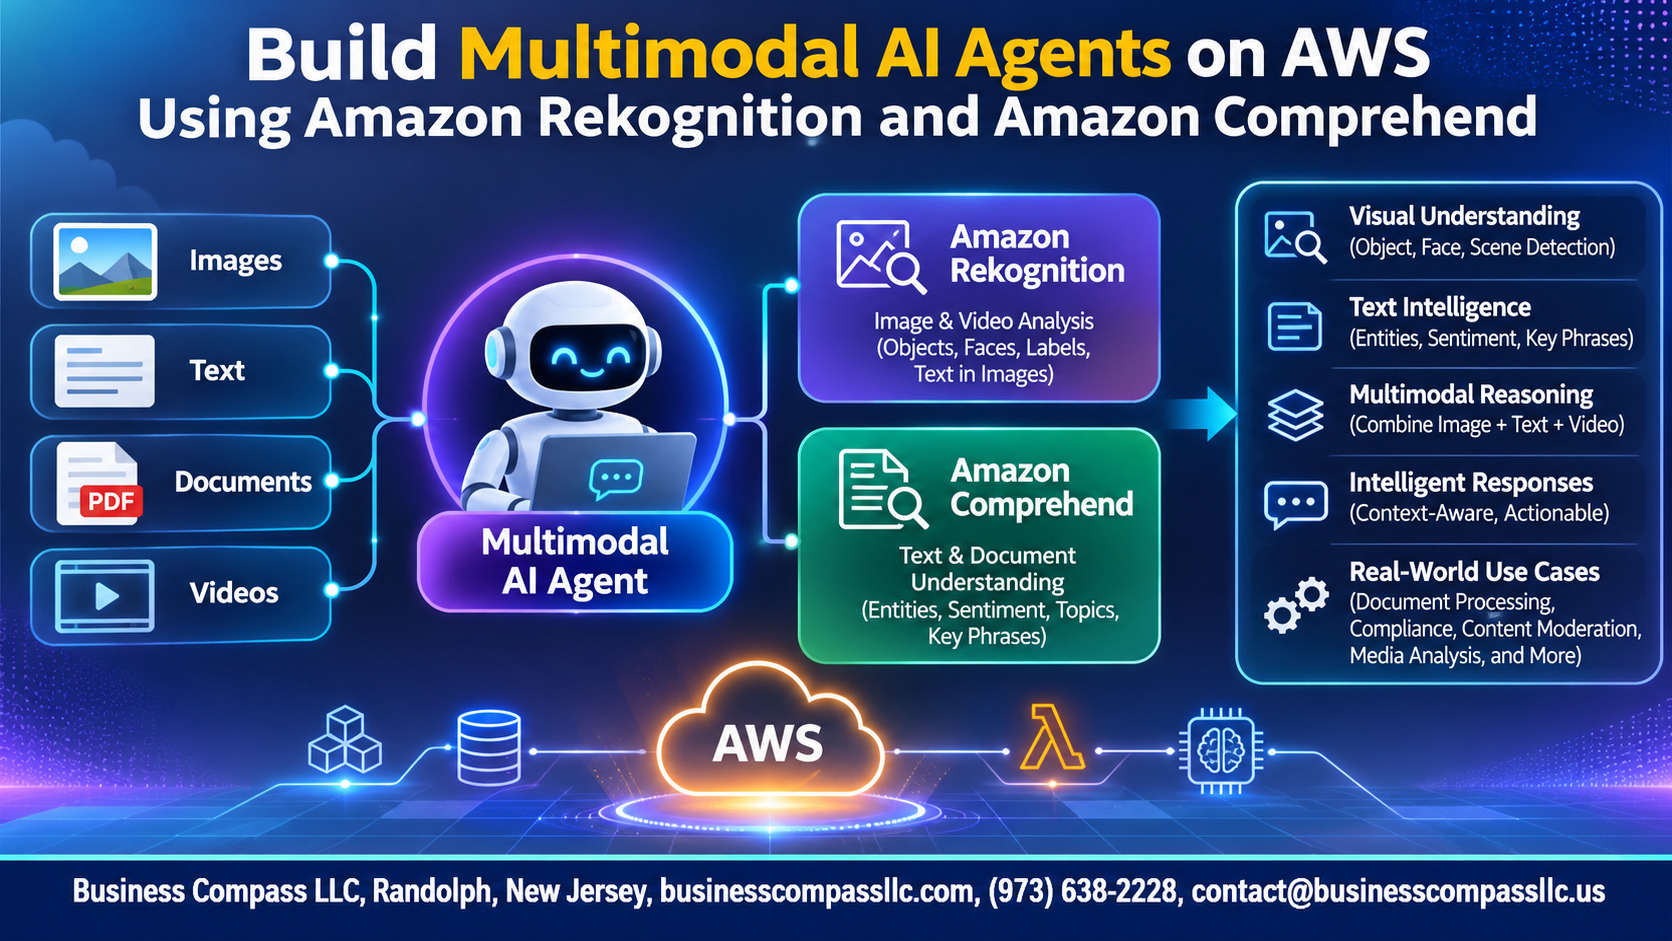
- Image and text analysis on AWS: Rekognition pulls out objects, faces, and scenes. Comprehend handles sentiment, key phrases, and entities. You’ll get a quick Amazon Rekognition tutorial and a look at Amazon Comprehend sentiment analysis.
- Scalable AI agent architecture: We’ll sketch a design that grows with your traffic, so you’re not rebuilding later.
- Fusing both modalities and shipping it: You’ll combine visual and language insights into one agent, then test, monitor, and deploy your AI agents on AWS with confidence.
By the end, you’ll have a clear path from a blank AWS account to a multimodal agent that runs in production. Grab your coffee and let’s get started.
Understand the Power of Multimodal AI Agents
Combine Vision and Language for Smarter Decisions
Multimodal AI agents read images and text together, so they catch what single-input systems miss.
Identify High-Value Business Use Cases
Think content moderation, insurance claims, and retail feedback.
See How Rekognition and Comprehend Complement Each Other
Amazon Rekognition spots objects and faces; Amazon Comprehend gets sentiment and entities.
Design a Scalable Multimodal Agent Architecture
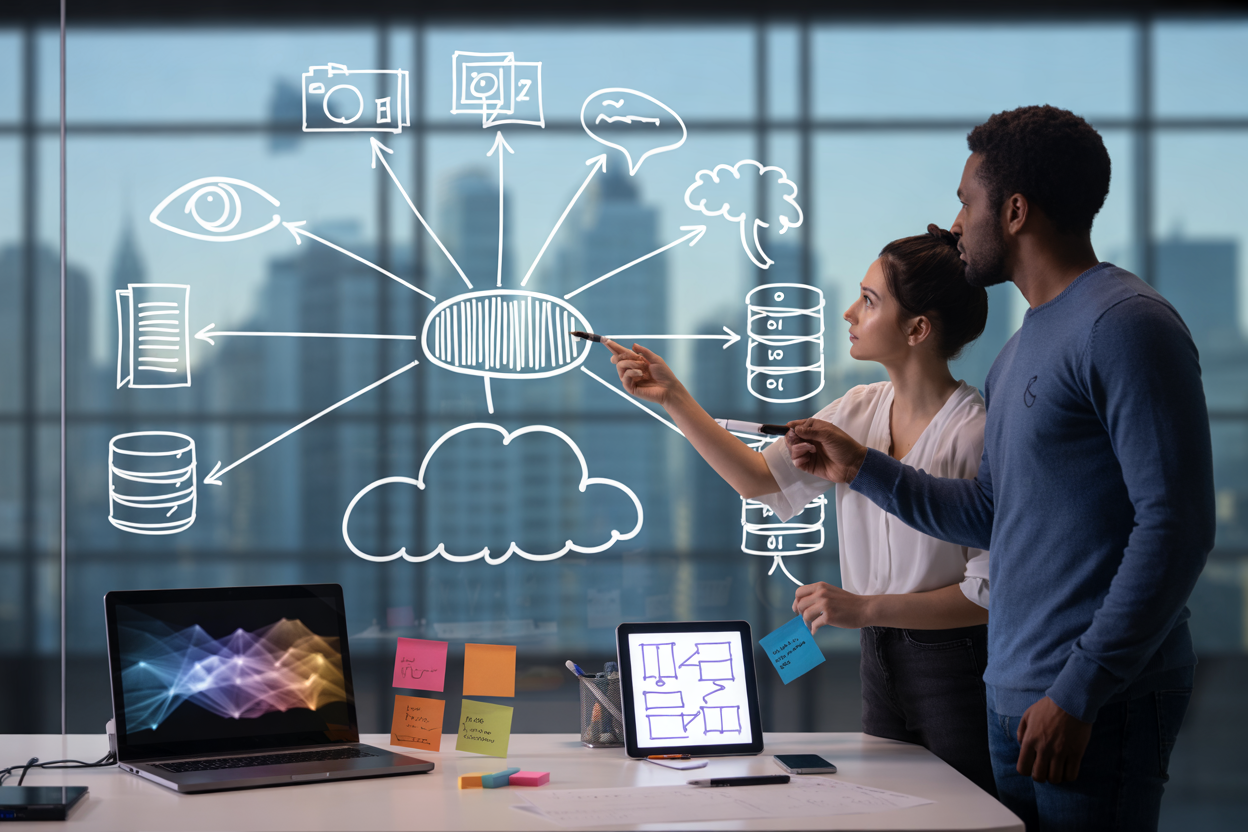
Map the End-to-End Agent Workflow
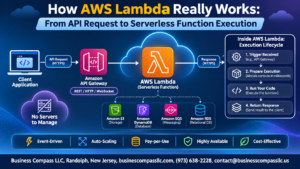
Upload, analyze, merge, respond.
Choose the Right AWS Services for Orchestration
Step Functions coordinate Lambda.
Plan Data Flow Between Image and Text Pipelines
Rekognition labels, Comprehend sentiment meet in DynamoDB.
Build Security and Cost Efficiency In From the Start
Least-privilege IAM, encryption, budgets.
Set Up Your AWS Environment Quickly
Configure IAM Roles and Permissions
Create one IAM role with least-privilege access to S3, Rekognition, and Comprehend.
Create S3 Buckets for Image and Text Inputs
Set up separate buckets for images and text, and turn on encryption.
Enable Rekognition and Comprehend APIs
Both services are ready to call by default. Just test them in your region.
Extract Visual Insights With Amazon Rekognition
Detect Objects, Scenes, and Faces
DetectLabels and DetectFaces spot what’s in each image.
Pull Text From Images Automatically
DetectText grabs signs and receipts.
Moderate Content to Keep Outputs Safe
DetectModerationLabels flags unsafe images early.
Turn Visual Output Into Structured Data
Save results as JSON with confidence scores.
Uncover Language Insights With Amazon Comprehend
Analyze Sentiment and Key Phrases
Score reviews, then pull key phrases.
Recognize Entities and PII
Spot people, brands, and mask PII.
Classify Documents With Custom Models
Train classifiers for your own categories.
Combine Extracted Image Text With Written Content
Send Rekognition’s detected text into Comprehend.
Fuse Modalities Into a Unified Agent
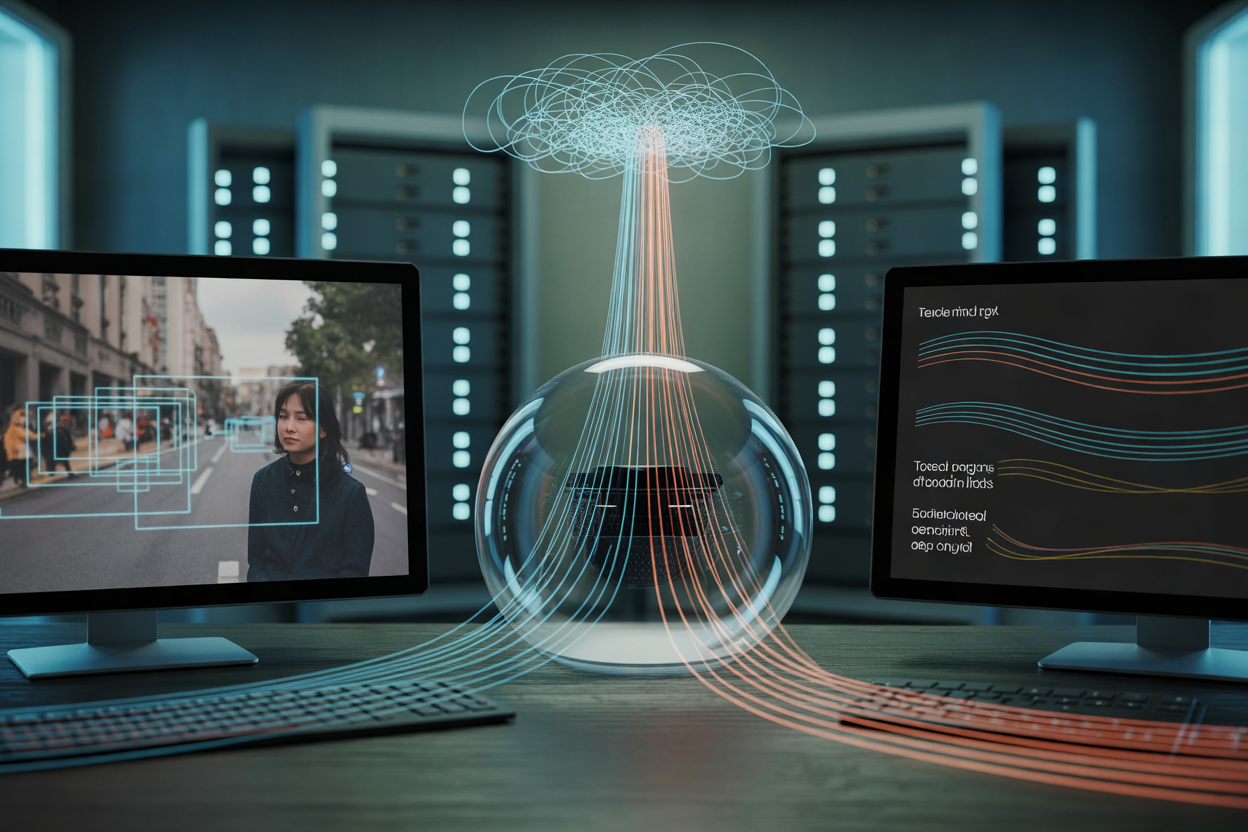
Merge Visual and Textual Signals Into One Context
- Combine labels and sentiment in one JSON.
Add Reasoning Logic With AWS Lambda and Step Functions
- Step Functions route decisions.
Integrate Amazon Bedrock for Intelligent Responses
- Bedrock drafts replies from context.
Trigger Automated Actions Based on Insights
- SNS alerts or tickets fire automatically.
Test, Optimize, and Monitor Performance
Validate Accuracy With Real-World Samples
Test with messy, real inputs: blurry photos, slang, sarcasm. Compare Rekognition labels and Comprehend sentiment against human-labeled samples.
Reduce Latency and Control Costs
Batch requests, cache repeat results, and call services in parallel.
Track Agent Health With CloudWatch
Watch latency, errors, and throttling, and set alarms.
Deploy and Scale With Confidence
Automate Deployment Using Infrastructure as Code
Define Lambda, S3, and IAM roles in AWS CDK or CloudFormation so every deploy matches.
Handle Growing Workloads With Event-Driven Scaling
Trigger Rekognition and Comprehend through S3 events, SQS, and Lambda to scale automatically.
Apply Best Practices for Responsible AI and Governance
Use least-privilege IAM, encryption, and human review for low-confidence results.
Multimodal AI agents get a lot smarter when they can see and read at the same time. With Amazon Rekognition handling images and video, and Amazon Comprehend making sense of text, you’ve got two powerful tools that work well together. Add a clean architecture, a quick AWS setup, and a solid way to fuse both streams of insight, and you end up with one agent that understands the full story instead of just half of it.
The rest comes down to good habits. Test your agent early, tweak it based on real results, and keep an eye on performance so small issues don’t turn into big ones. When you’re ready, deploy and scale step by step.
So don’t wait for the perfect plan. Pick one small use case, like analyzing product photos and customer reviews together, and build a simple prototype this week. You’ll learn more from that first working version than from any amount of planning.