

Stop Babysitting Your Servers: Build a Self-Healing AWS Infrastructure with Terraform
If your web app goes down every time traffic spikes, you don’t have an infrastructure problem — you have a design problem.
This Terraform AWS tutorial is for developers and DevOps engineers who want to build a highly available web architecture that scales automatically, recovers from failures on its own, and doesn’t require you to be on-call every weekend. No manual clicking around the AWS console. No single points of failure. Just clean, repeatable AWS infrastructure as code that actually holds up under pressure.
Here’s what we’ll walk through together:
- Building a secure network foundation — VPCs, subnets, and routing that give your app room to grow without exposing it to the open internet
- Setting up an Application Load Balancer — so traffic gets distributed evenly across your instances and unhealthy servers get pulled out of rotation automatically
- Configuring Auto Scaling — so your AWS deployment adds capacity when demand jumps and scales back down when things quiet down, keeping costs in check
By the end, you’ll have a scalable AWS deployment running behind a load balancer, managed entirely through Terraform, and ready to handle real-world traffic without you lifting a finger.
Let’s build it.
Understanding the Core Components of a Highly Available AWS Infrastructure
Why High Availability Matters
Modern web apps can’t afford downtime — lost revenue, frustrated users, and damaged trust follow instantly.
Key AWS Services
- ALB, Auto Scaling, VPC, EC2
Terraform’s Role
Terraform automates your entire AWS high availability infrastructure through reusable, version-controlled code.
Architecture Snapshot
Multi-AZ deployment with ALB distributing traffic across auto-scaled EC2 instances.
Setting Up Your Terraform Environment for AWS
A. Installing and Configuring Terraform Locally
- Download Terraform from terraform.io and add it to your PATH.
B. Configuring AWS Credentials and Provider Settings
- Run
aws configurewith your access keys.
C. Structuring Your Terraform Project for Scalability
- Split files:
main.tf,variables.tf,outputs.tf.
Building a Secure and Scalable Network Foundation
Creating a VPC with Public and Private Subnets
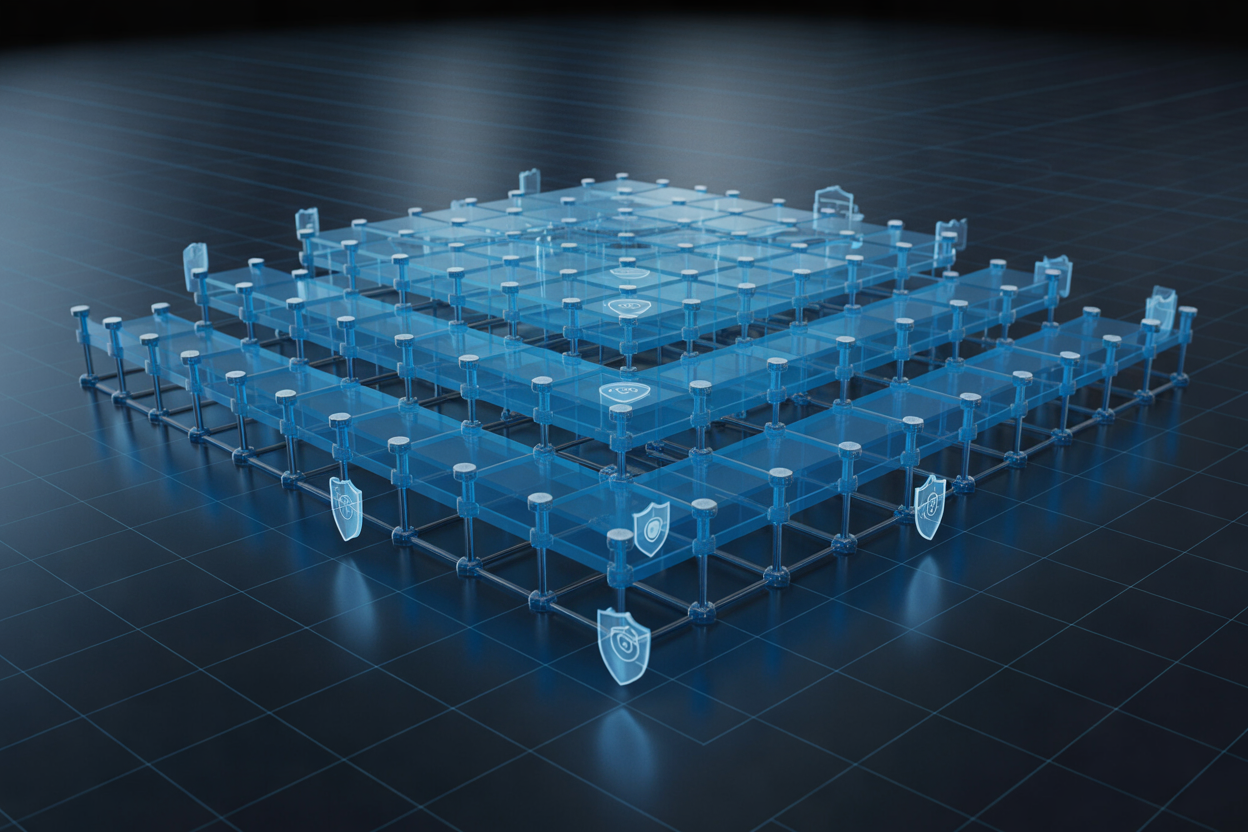
Define your AWS network foundation using Terraform’s aws_vpc resource, splitting workloads across public subnets (load balancers) and private subnets (application servers).
Configuring Internet Gateways and Route Tables
- Attach an Internet Gateway to your VPC
- Route public subnet traffic through it
Setting Up Security Groups
Restrict inbound rules tightly — ALB accepts port 80/443; EC2 instances only accept traffic from the ALB security group.
Enabling Multi-AZ Deployment
Spread subnets across at least two Availability Zones for fault tolerance.
Deploying and Configuring the Application Load Balancer
Defining the ALB Resource and Listener Rules in Terraform
Configure your Application Load Balancer setup using aws_lb and aws_lb_listener resources, routing HTTP/HTTPS traffic to target groups with path-based rules.
Setting Up Target Groups
- Use
aws_lb_target_groupwith port 80 - Enable sticky sessions if needed
Enabling Health Checks
Set healthy/unhealthy thresholds, paths, and intervals to keep routing reliable across your scalable AWS deployment.
Implementing Auto Scaling for Dynamic Capacity Management
Creating a Launch Template with Optimized EC2 Configuration
Define your EC2 instance type, AMI, and user data scripts here.
Defining Auto Scaling Group Settings for Maximum Resilience
- Set min/max/desired capacity across multiple AZs
Configuring Scaling Policies
Target tracking on CPU usage keeps costs tight.
Linking ASG to ALB
Attach target groups directly for seamless Terraform ALB auto scaling.
Validating and Testing Your High Availability Setup
Applying Your Terraform Configuration and Verifying Resources
Run terraform apply and check the AWS Console to confirm your ALB, Auto Scaling group, and EC2 instances are live.
Simulating Traffic Spikes to Confirm Auto Scaling Triggers
Use Apache Bench or Locust to hammer your ALB endpoint and watch new instances spin up automatically.
Testing Failover Scenarios to Prove Multi-AZ Reliability
Terminate instances in one AZ — traffic should instantly reroute across healthy AZs without downtime.
Optimizing Cost and Performance of Your AWS Infrastructure
Leveraging Spot Instances to Reduce Auto Scaling Costs
Mix Spot and On-Demand instances in your Auto Scaling group using a mixed instances policy to cut costs by up to 70%.
Using CloudWatch Metrics to Fine-Tune Scaling Thresholds
Track CPU, memory, and request counts to dial in scaling policies.
Applying Tagging Strategies for Better Cost Allocation
Tag resources by environment, team, and project for clean AWS Cost Explorer breakdowns.
Building a highly available AWS infrastructure doesn’t have to be overwhelming. By combining Terraform’s infrastructure-as-code capabilities with ALB’s intelligent traffic distribution and Auto Scaling’s dynamic capacity management, you have everything you need to keep your applications running smoothly — even when traffic spikes or individual components fail. From laying down a solid network foundation to validating your setup under real-world conditions, each piece of this puzzle plays a critical role in keeping your system resilient and cost-efficient.
Now it’s time to put this into practice. Start small, test often, and keep an eye on your cost and performance metrics as you scale. The setup you’ve built here isn’t just a one-time project — it’s a foundation you can continuously improve as your application grows. Take what you’ve learned, spin up your Terraform configurations, and start building infrastructure that can handle whatever comes its way.