

Build a Real Sales Analytics Pipeline on AWS Without Managing Servers
If you work with sales data and spend too much time wrangling spreadsheets or waiting on your data team, this project is for you. Data engineers, cloud developers, and analytics-focused developers who want hands-on AWS experience will get the most out of this guide.
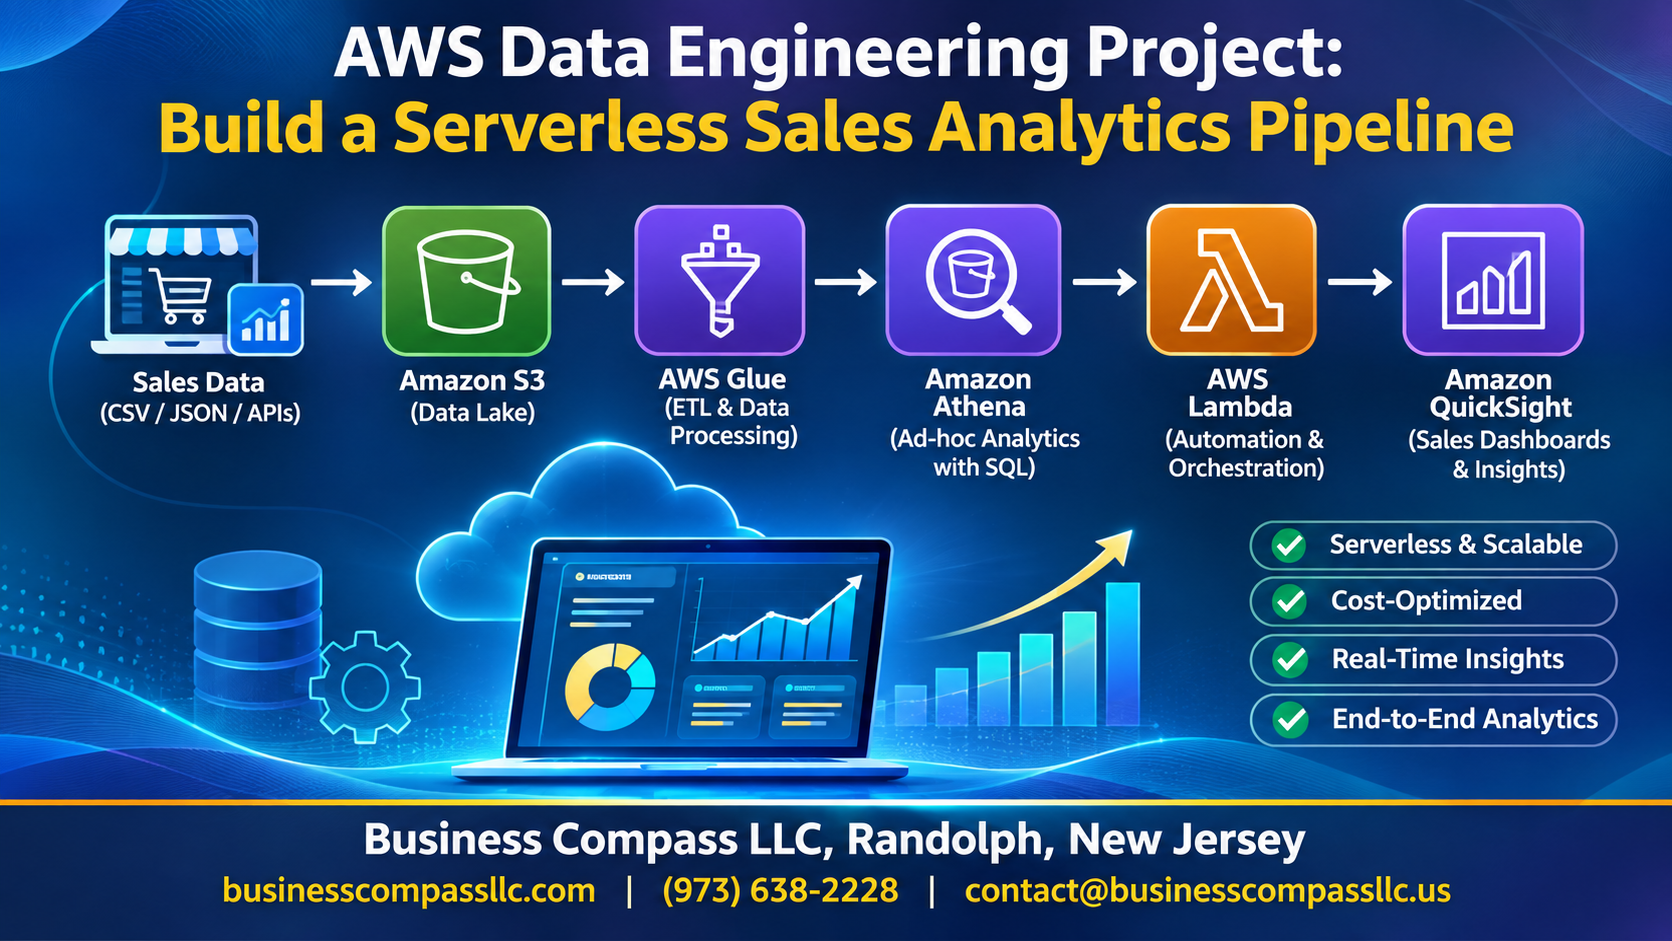
We’re building a fully functional AWS serverless data pipeline that pulls in raw sales data, cleans it up, and turns it into dashboards your team can actually use — no servers to babysit, no infrastructure headaches.
Here’s what we’ll walk through together:
- How the pipeline fits together — you’ll see the full sales analytics AWS architecture before writing a single line of code, so nothing feels random later
- Getting data in and transforming it — we’ll use AWS Lambda, S3, and AWS Glue data processing to move raw sales records from messy to query-ready
- Turning data into decisions — Amazon Athena handles the querying, and QuickSight handles the visuals, so stakeholders get answers fast
By the end, you’ll have a pipeline that runs automatically, scales on its own, and doesn’t need you to babysit it at 2 a.m. Let’s get into it.
Understanding the Serverless Sales Analytics Pipeline Architecture
Key AWS Services That Power the Pipeline
- Lambda, S3, Glue, Athena, QuickSight
How Serverless Architecture Reduces Cost and Complexity
Pay only for actual usage—no idle servers.
Overview of Data Flow From Ingestion to Insight
Raw sales data lands in S3, AWS Glue data transforms it, and Athena queries feed QuickSight dashboards, making your AWS serverless data pipeline surprisingly straightforward for sales analytics AWS workloads.
Setting Up Your AWS Environment for Success
Configuring IAM Roles and Permissions Securely
Create least-privilege roles for Lambda, Glue, and Athena — no wildcards.
Organizing S3 Buckets for Raw and Processed Sales Data
sales-raw/→ landing zonesales-processed/→ transformed output
Enabling AWS Regions and Service Quotas
Pick one region; request Glue and Lambda quota increases early.
Structuring for Scalability
Prefix S3 paths by date for efficient AWS Glue data partitioning.
Ingesting Sales Data With AWS Lambda and S3
Automating Data Uploads Using S3 Event Triggers
Configure S3 buckets to fire events whenever new sales files land, automatically kicking off your AWS serverless data pipeline.
Writing Lambda Functions to Validate and Route Incoming Data
Lambda checks file format, flags bad records, and routes clean data to the right S3 prefix.
Handling Real-Time and Batch Sales Data Efficiently
- Stream transactions instantly
- Schedule bulk CSV drops nightly
Transforming and Processing Data With AWS Glue
Building Glue ETL Jobs to Clean and Standardize Sales Records
AWS Glue ETL jobs strip messy raw sales data of duplicates, null values, and formatting inconsistencies, outputting clean Parquet files to S3. Pair these with Glue Crawlers to auto-catalog schemas, partition data by date/region for faster Athena queries, and use job bookmarks to cut runtime costs on your AWS serverless data pipeline.
Querying Sales Insights With Amazon Athena
Writing SQL Queries to Uncover Key Sales Trends
Run standard SQL against your AWS Glue Data Catalog to pull revenue, top products, and regional performance.
Reducing Query Costs by Leveraging Partitioned Data
Athena scans only relevant partitions, cutting costs dramatically in your sales analytics AWS pipeline.
Saving and Reusing Queries for Recurring Business Reports
Save named queries for weekly reports—no rewrites needed.
Visualizing Sales Analytics With Amazon QuickSight
Connecting QuickSight to Athena, Building Dashboards, and Sharing Insights
Connect QuickSight directly to your Athena data source, then build dashboards tracking revenue trends, top-performing products, and regional sales. Share real-time insights with stakeholders through scheduled email reports or embedded links—turning your AWS serverless data pipeline into a complete sales analytics AWS solution that drives smart business decisions fast.
Automating and Monitoring the Pipeline for Reliability
Scheduling Pipeline Runs With Amazon EventBridge
Use EventBridge rules to trigger your AWS serverless data pipeline on a cron schedule.
Setting Up CloudWatch Alarms
Monitor Lambda errors, Glue job failures, and S3 activity with targeted alarms and SNS notifications.
Logging and Testing
- Enable AWS Glue data job logs in CloudWatch
- Run end-to-end tests with sample sales analytics AWS data before going live
Building a serverless sales analytics pipeline on AWS brings together some seriously powerful tools — Lambda, S3, Glue, Athena, and QuickSight — each playing a specific role in turning raw sales data into actionable insights. From setting up your environment to automating and monitoring the entire workflow, every step builds on the last to create a pipeline that’s scalable, cost-effective, and surprisingly low-maintenance once it’s up and running.
The best part? You don’t need a massive infrastructure team or expensive servers to make this work. Start small, get familiar with each service, and gradually refine your pipeline as your data needs grow. If you haven’t started yet, pick one piece of the architecture and build from there — even a basic Lambda function writing data to S3 is a solid first step toward a fully automated sales analytics setup.