

Inside the Ingestion API: How Trip Files Are Uploaded, Validated, and Processed
If you’re a developer or data engineer working with fleet or mobility data, you’ve probably asked: what actually happens after a trip file gets sent to the system? The ingestion API is the backbone of that process — it’s what receives raw trip data, checks it for errors, and hands it off for downstream processing.
This guide breaks down exactly how that works. You’ll get a clear look at how trip files move through the upload process, what the validation layer checks before accepting a file, and how the system handles processing once a file clears those checks. By the end, you’ll know where things can go wrong and what to watch for when something does.
What the Ingestion API Does and Why It Matters
The Role of the Ingestion API in Managing Trip Data
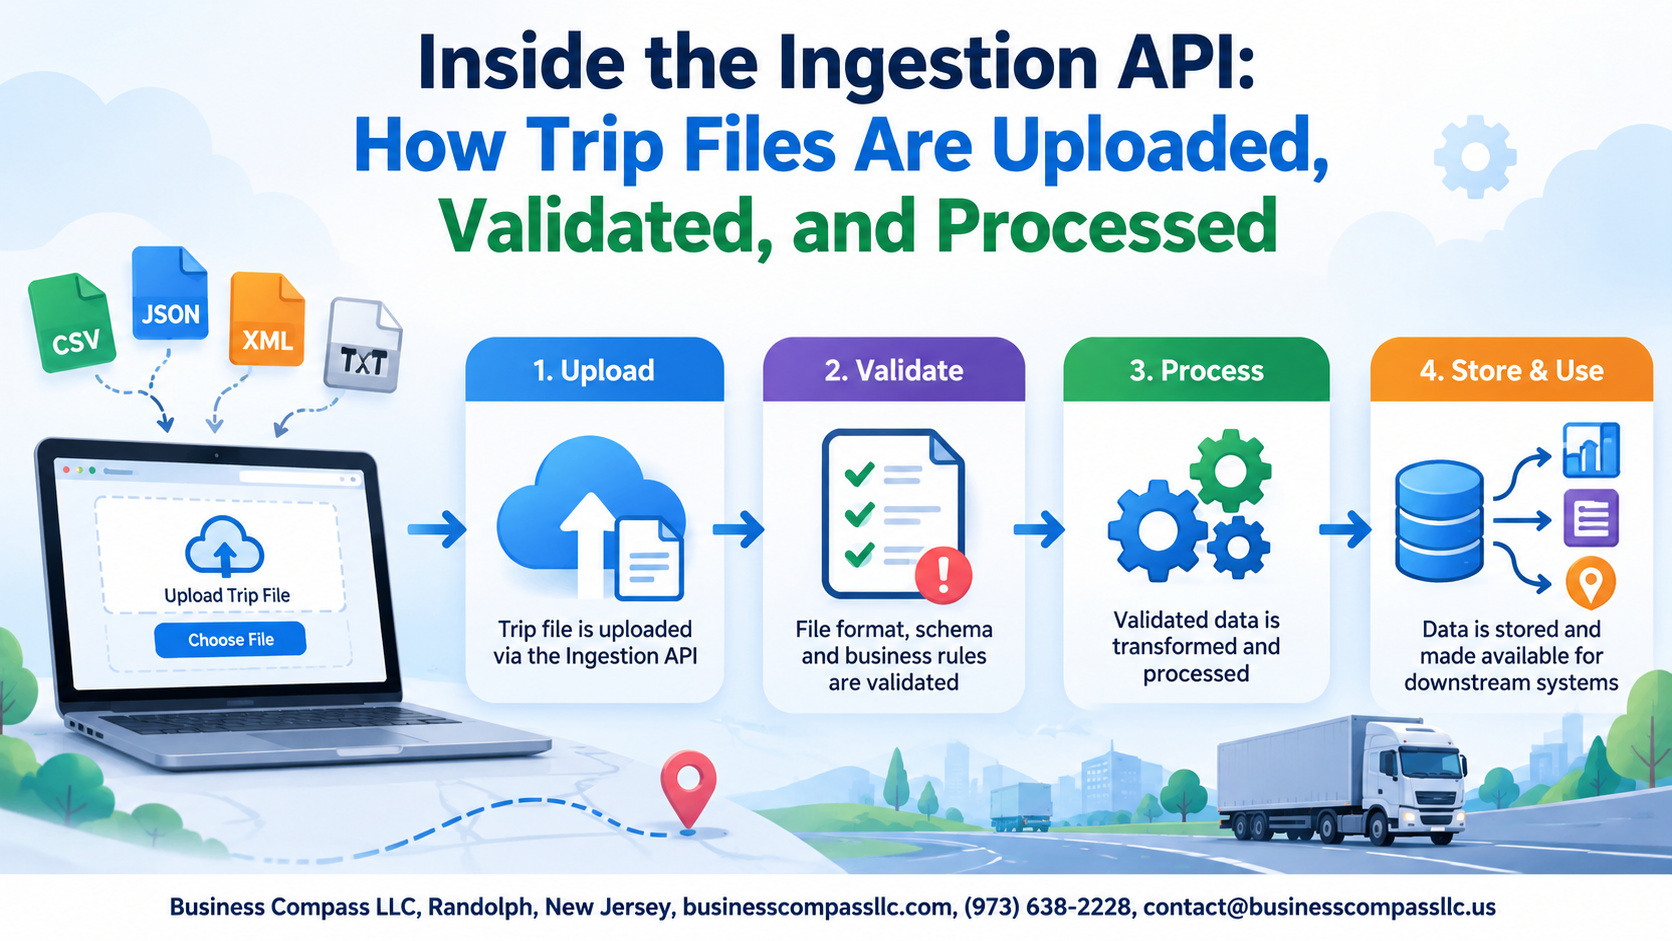
The Ingestion API handles trip file uploads, validates data accuracy, and routes clean files for processing — all in one streamlined data ingestion pipeline.
Key Benefits of a Centralized Upload and Processing Pipeline
- Consistent validation rules
- Faster error detection
- Reliable trip data processing at scale
How the API Fits Into the Broader Data Infrastructure
It connects upstream file sources directly to downstream analytics, keeping everything synchronized.
How Trip Files Are Uploaded to the System
Supported File Formats and Data Structures
Trip files are accepted as JSON, CSV, or XML.
Authentication and Authorization Before Upload
API keys plus OAuth tokens gate every request.
Handling Large Files and Batch Submissions Efficiently
Multipart uploads and chunked batches keep the data ingestion pipeline moving without timeouts.
Error Responses When Uploads Fail at Entry
Failed trip file uploads return clear HTTP error codes — 400, 401, or 413 — pinpointing the exact problem instantly.
Validating Trip Files for Accuracy and Completeness
Schema Validation Rules That Every File Must Pass
Every trip file hitting the Ingestion API gets checked against strict schema rules — required fields, correct data types, and valid formats. Duplicate records are caught early, malformed entries flagged instantly, and developers get real-time feedback pinpointing exact errors. Rejected files can be fixed and cleanly resubmitted without restarting the full pipeline.
Processing Trip Files After Successful Validation
How Validated Data Moves Through the Processing Pipeline
Once the data ingestion pipeline clears a trip file, it queues automatically for processing — no manual handoff needed.
Transforming Raw Trip Data Into a Usable Format
- Timestamps normalize, coordinates map, and fields standardize
Triggering Downstream Systems and Workflows Automatically
- Alerts, billing, and analytics kick off instantly after trip file processing completes
Monitoring and Troubleshooting the Ingestion Pipeline
Key Metrics, Bottlenecks, Logs, and Best Practices
Track throughput, error rates, and latency across your data ingestion pipeline. Watch for spikes in failed trip file uploads or validation rejections. Use structured logs and real-time alerts to catch issues before they snowball. Schedule regular audits, set retry limits, and keep your Ingestion API dependencies updated for a smooth, reliable workflow.
The Ingestion API plays a critical role in keeping trip data accurate, complete, and ready to use. From the moment a file is uploaded to the system, every step — validation, processing, and monitoring — works together to make sure bad data doesn’t slip through and cause problems down the line. When each part of the pipeline does its job, the result is clean, reliable data that teams can actually trust.
If you’re working with trip files regularly, getting familiar with how the ingestion process works is a smart move. Knowing what happens at each stage helps you catch issues faster, troubleshoot with confidence, and keep the pipeline running smoothly. The better you understand the system, the less time you’ll spend chasing down data errors and the more time you’ll have to focus on what the data is actually telling you.